The card sits in front of the first prompt
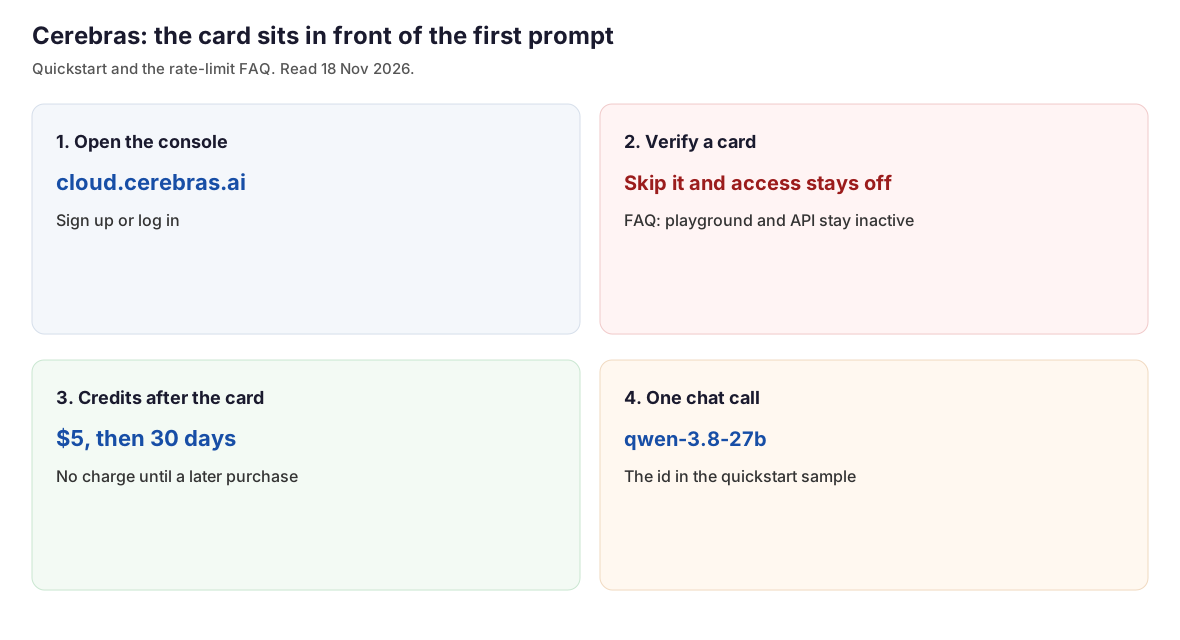
On 18 November 2026 the rate-limit FAQ printed two different sentences. One says new accounts receive $5 in free credits after a verified payment method is added, that the credits expire 30 days after they are granted, and that they can be spent on public models. The next clause says there is no charge until you purchase additional credits. A separate sentence says that skipping the payment method at sign-up leaves playground and API access inactive until you add one. "Verified" is attached to the $5. "Add" is the word on the sentence that keeps the playground off.
The quickstart, fetched the same day, says the playground in the Cloud Console needs no key and no install. That line does not mention a payment method. No account was created for this page, so no payment form was submitted.
 🔍 View full resolution
Sign up: cloud.cerebras.ai
Rate-limit FAQ: inference-docs.cerebras.ai/support/rate-limits
Once the key exists, the sample model is qwen-3.8-27b
The quickstart then says to open API Keys in the left nav, create a key, and export CEREBRAS_API_KEY. The sample completion sets model to qwen-3.8-27b and posts to https://api.cerebras.ai/v1/chat/completions. The header is Authorization: Bearer plus that variable. GET https://api.cerebras.ai/v1/models with no key returned HTTP 403 and the body {"detail":"Not authenticated"}. That 403 is this catalog request. The quickstart's 401 note is a different request: a chat completion whose shell is missing CEREBRAS_API_KEY. The same notes say 404 when the model id is misspelled, deprecated, or absent from the account, and 429 when a rate limit is hit. No chat completion was sent, so the 401, 404, and 429 lines were not reproduced here.
Get a key: inference-docs.cerebras.ai/console/api-keys
Quickstart: inference-docs.cerebras.ai/quickstart
Two free-trial rows, valid while the $5 lasts
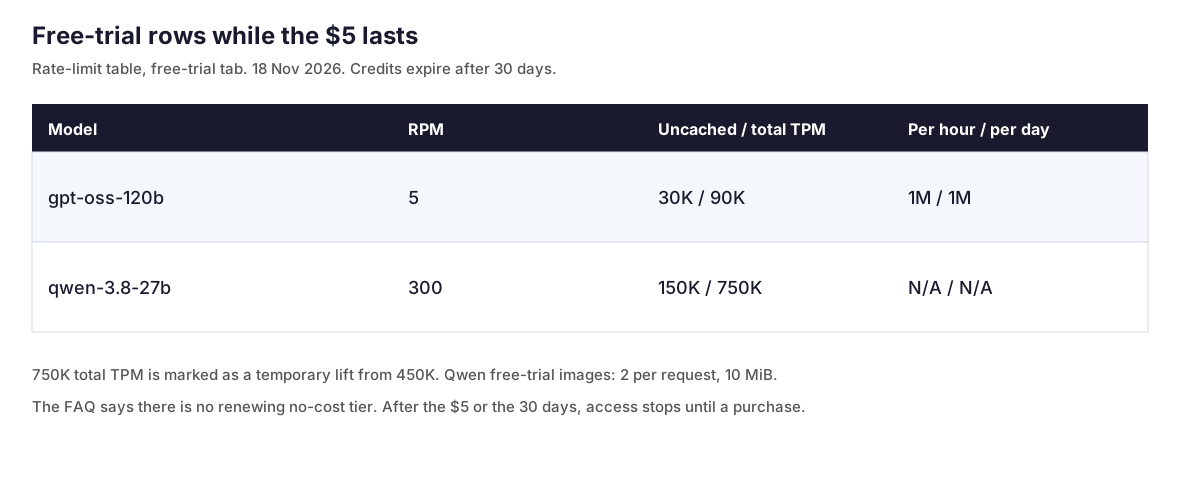
The free-trial tab says the numbers below apply while you use the $5 in free-trial credits. Two models are printed.
 🔍 View full resolution
| Model | RPM | Uncached TPM | Total TPM | Per hour | Per day |
|---|---|---|---|---|---|
| gpt-oss-120b | 5 | 30K | 90K | 1M | 1M |
| qwen-3.8-27b | 300 | 150K | 750K | N/A | N/A |
The qwen total of 750K TPM is marked as a temporary lift from 450K, described as 3 times uncached, to 750K, described as 5 times uncached. The note names Qwen 3.8 27B only: its per-minute request and token limits match pay as you go, and hourly and daily token caps do not apply to that model on either tier. gpt-oss-120b does not share those numbers. On the free-trial row it is 5 requests a minute and 30K uncached TPM. On the developer row it is 1,000 requests a minute and 500K uncached TPM. The free-trial image note on that row is 2 images per request and a 10 MiB payload. On the developer table the image note is 10 images per request, still 10 MiB.
Developer (pay as you go) numbers on the same page: gpt-oss-120b is 500K uncached TPM, 1.5M total TPM, and 1,000 requests a minute. qwen-3.8-27b is 150K uncached TPM, 750K total TPM, and 300 requests a minute. Hourly and daily restrictions do not apply on that tier. Token use can keep going inside the budget and inside those per-minute caps.
Rate limits: inference-docs.cerebras.ai/support/rate-limits
Which call to send
Choose qwen-3.8-27b if the first request should match the quickstart sample. The free-trial row is 300 requests a minute, 150K uncached tokens a minute, and 750K total tokens a minute. The hourly and daily cells are N/A.
Quickstart: inference-docs.cerebras.ai/quickstart
Choose gpt-oss-120b if the job fits inside 5 requests a minute, 30K uncached tokens a minute, 90K total tokens a minute, 1 million tokens an hour, and 1 million tokens a day, for as long as the $5 trial lasts.
Buy credits if the $5 is gone or the 30 days are gone. The FAQ says access stops until credits are purchased, that keys and projects remain, and that the first purchase moves the account to the developer tier. Per-model minute limits still apply. The same FAQ says Cerebras does not currently offer a no-cost tier that renews on its own, and does not offer a per-model always-free allowance.
Model catalog: inference-docs.cerebras.ai/models/overview
Sign up: cloud.cerebras.ai