The $0.75 line, and what counts as one
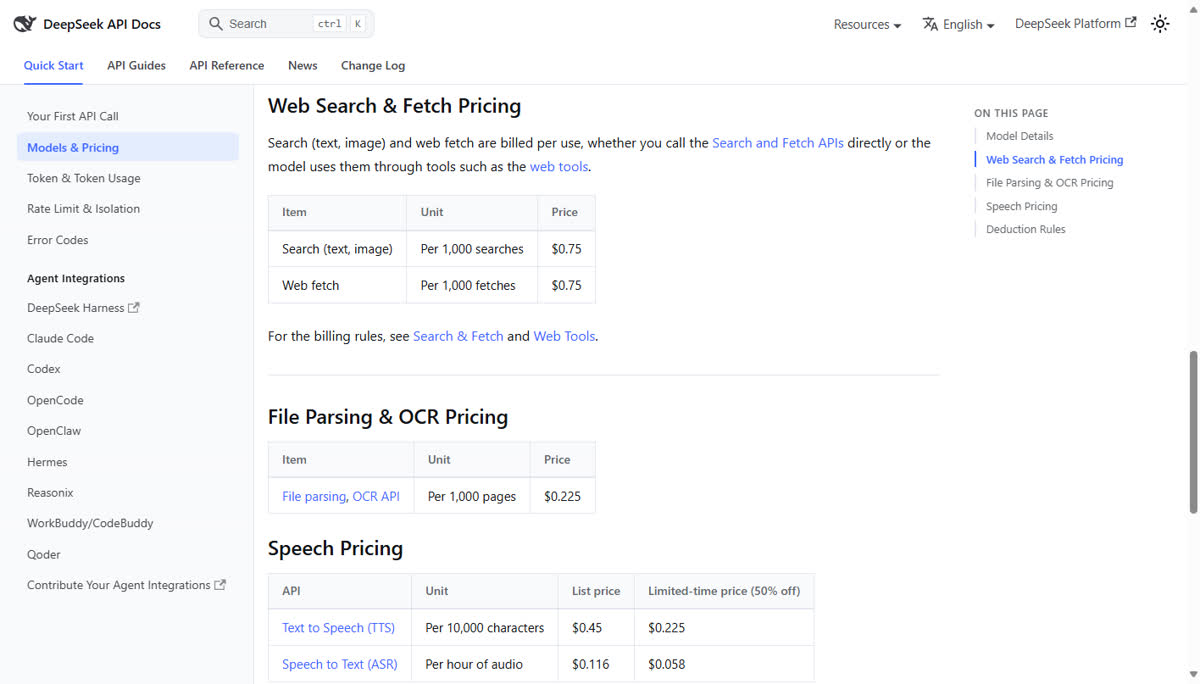
The DeepSeek Models and Pricing page, fetched 15 November 2026, prices search (text and image) at $0.75 per 1,000 searches and web fetch at $0.75 per 1,000 fetches. One successful call is $0.00075. The page says this unit price applies whether the caller hits the Search and Fetch APIs directly or the model triggers them through the web tools.
 🔍 View full resolution
The Search and Fetch guide splits the direct APIs from that shared unit price. A direct request is billed only when it returns HTTP 200 and a result: Search needs a non-empty results array, Fetch needs page content. Failed requests, empty results, and timeouts are not billed. The count parameter, from 1 to 50, only changes how many rows come back. It does not change the per-request price.
The same guide sets account-level QPS, counted across keys, separate from model concurrency: Search 100, Fetch 25. Traffic on one does not spend the other. Over the limit the response is HTTP 429. Fetch also has a per-domain QPS limit, and the page does not print that domain number.
Signup: platform.deepseek.com/api_keys
Pricing: api-docs.deepseek.com/quick_start/pricing
Search rules: api-docs.deepseek.com/guides/search
Token rates that sit beside the tool fee
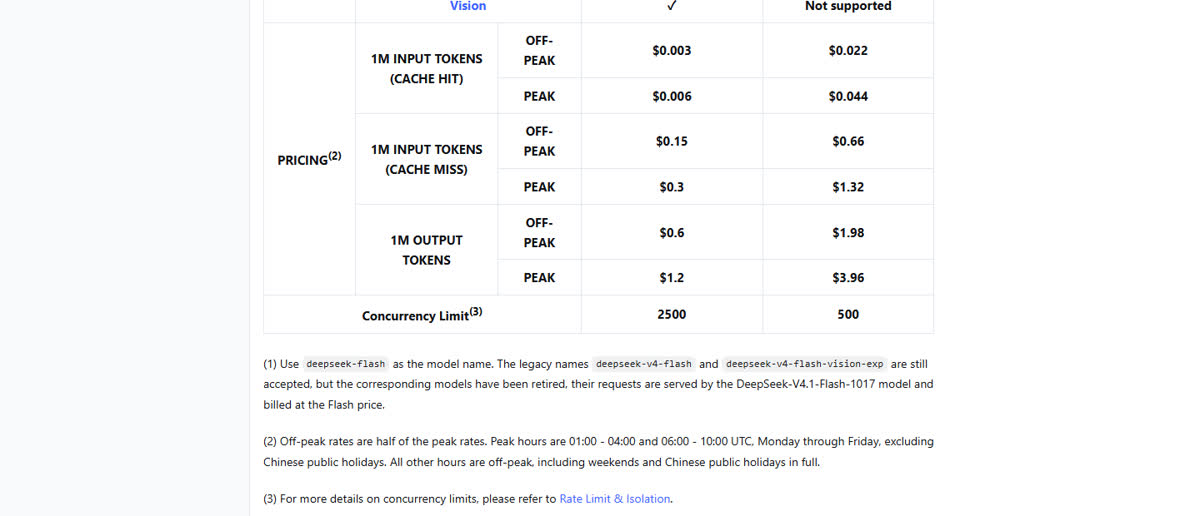
Tool fees do not include tokens. The model table on the same page lists two names: deepseek-flash (version DeepSeek-V4.1-Flash-1017) and deepseek-v4-pro (DeepSeek-V4-Pro-0813). Context is 1M tokens. Max output is 384K. Flash concurrency is 2,500. Pro concurrency is 500. Legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp still route, and the page says those requests are served by V4.1-Flash-1017 and billed at the Flash price.
 🔍 View full resolution
| Item | Flash off-peak | Flash peak | Pro off-peak | Pro peak |
|---|---|---|---|---|
| 1M input, cache hit | $0.003 | $0.006 | $0.022 | $0.044 |
| 1M input, cache miss | $0.15 | $0.30 | $0.66 | $1.32 |
| 1M output | $0.60 | $1.20 | $1.98 | $3.96 |
| Search or fetch | $0.75 per 1,000 successful uses, no peak column | |||
| File parsing, OCR | $0.225 per 1,000 pages | |||
Footnote 2 on the page says off-peak rates are half of peak rates. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. Weekends and Chinese public holidays stay off-peak the whole day. 15 November 2026 is a Sunday, so the off-peak column is the one in force for the whole date.
Speech is a separate table, and the page labels the lower column as a limited-time 50 percent price: TTS $0.225 per 10,000 characters against a $0.45 list price, ASR $0.058 per hour of audio against $0.116. That column is not a standing rate.
One step, priced on the Sunday column
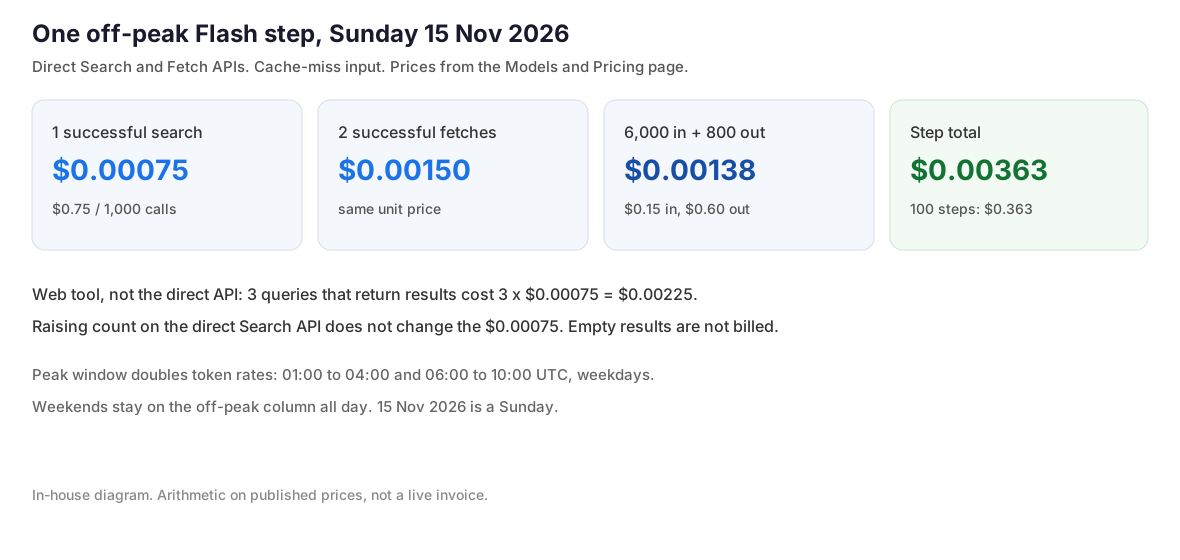
Take a direct-API step on off-peak Flash, cache-miss input: 1 successful search, 2 successful fetches, 6,000 input tokens, 800 output tokens.
 🔍 View full resolution
Search is $0.00075. Two fetches are $0.00150. Input is 0.006 x $0.15 = $0.00090. Output is 0.0008 x $0.60 = $0.00048. Tokens together are $0.00138. The step is $0.00363. One hundred of those steps are $0.363.
The same 6,000 input tokens in the weekday peak window cost $0.00180, because cache-miss input moves from $0.15 to $0.30. Output in that window moves from $0.60 to $1.20, so the 800 output tokens cost $0.00096. The tool lines do not have a peak column.
Swap the tokens to off-peak Pro and the 800 output tokens cost 0.0008 x $1.98 = $0.001584, against $0.00048 on Flash. The output rate is 3.3 times the Flash rate ($1.98 / $0.60). Pro's concurrency cap on the page is 500, against 2,500 on Flash.
The web-tools guide counts differently from the direct API. A search call that returns results is billed for each of its queries, so three queries cost $0.00225, not $0.00075. A call that fails or returns nothing is not billed. Opening a page is billed when it is fetched from the web. Opening that same page again, moving through it, or reading a page that already arrived with the search results is free. Finding text inside a page is free. In usage.server_tool_use, the billed counters are tool_search, tool_fetch, and tool_image_search. The fields web_search_requests and web_fetch_requests include errors and the page says they are not the billed counts.
Web tool rules: api-docs.deepseek.com/guides/web_tools
Which call to spend
Choose the direct Search API if: the query is already written and up to 50 results are enough. One successful response is $0.00075 no matter the count. Account QPS is 100.
Choose direct Fetch if: the URL is already known. One successful page is $0.00075, and the account QPS is 25, separate from Search.
Choose the web search tool with thinking off if: the model should pick the queries. Budget one charge per query that returns results. Three queries are $0.00225 before any page is opened.
Choose deep thinking search if: one results list is not enough and the model has to open pages while it works. Newly fetched pages bill. A second open of the same page does not. Text search inside a page does not.
Keep the tokens on off-peak Flash if: the output bill is the constraint. Off-peak output is $0.60 per million tokens on Flash and $1.98 on Pro. Leave the speech 50 percent column out of a standing budget. The page marks it as limited-time.