Four facts on the model card
On 16 November 2026 the GLM-4.7-Flash model card puts four facts in the header: input is text, output is text, the context window is 200K, and the maximum output is 128K. The overview describes it as a 30B-class model and aims it at agentic coding. The capability row lists thinking mode, streaming, function calling, context caching, structured output, and MCP.
A later block on the same page discusses cameras and live visual input. That block does not change the header cells, which stay text in and text out. The pricing page lists a separate display name, GLM-4.6V-Flash, with free cells for input, output, and cache hits. That row does not print an API model string. The context cell has no number.
 🔍 View full resolution
Model card: docs.bigmodel.cn/cn/guide/models/free/glm-4.7-flash
The key has to match this endpoint
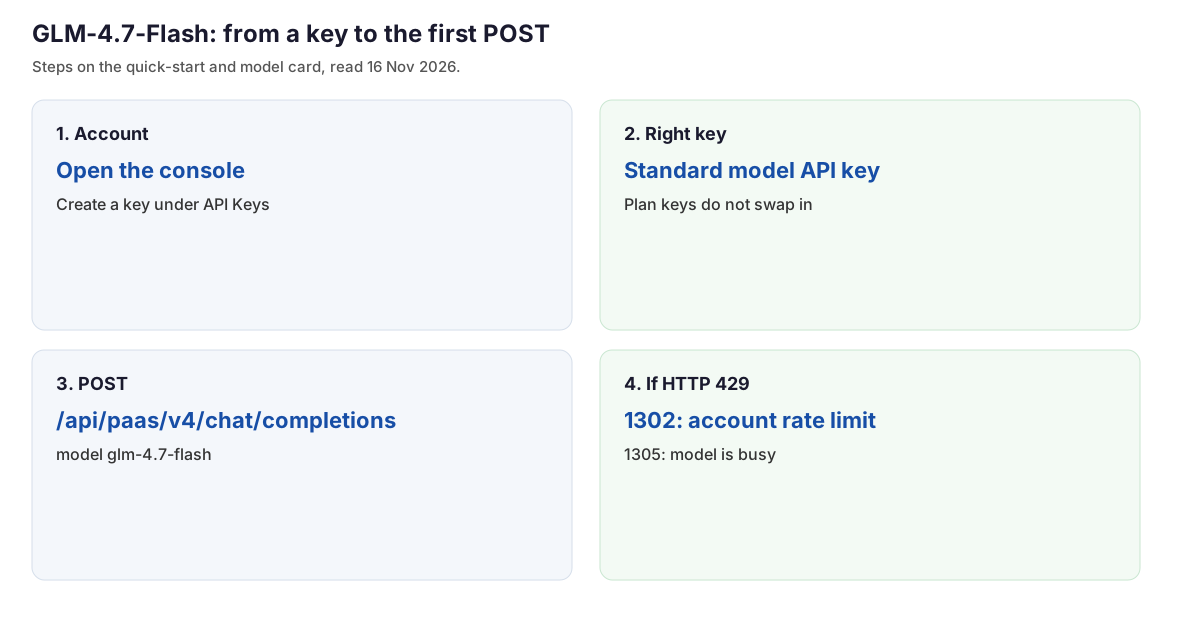
The quick start is short. Two lines in it decide whether the first call is accepted. Register on the console, open API Keys in the account center, and create a key. Personal-plan keys, team-plan keys, and standard model-API keys are kept separate. The page says the three types do not substitute for one another. Coding Plan is a further note on that page: it uses its own tutorial and endpoint. The page does not place Coding Plan inside the three key types.
Coding Plan traffic is sent to its own tutorial and endpoint. The sample for this model posts to https://open.bigmodel.cn/api/paas/v4/chat/completions with a bearer token and "model": "glm-4.7-flash". That sample sets thinking.type to enabled, max_tokens to 65536, and temperature to 1.0. The prompt in the doc is a longer multi-turn example. The fields above are the ones the sample actually sets. The Python tab installs zai-sdk, and it also shows the pin zai-sdk==0.2.3.
curl -X POST "https://open.bigmodel.cn/api/paas/v4/chat/completions" \
  -H "Authorization: Bearer $API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"glm-4.7-flash","messages":[{"role":"user","content":"hi"}],"thinking":{"type":"enabled"},"max_tokens":65536,"temperature":1.0}'
Create a key: open.bigmodel.cn/usercenter/apikeys
Quick start: docs.bigmodel.cn/cn/guide/start/quick-start
The price row says free. A 429 still has a code
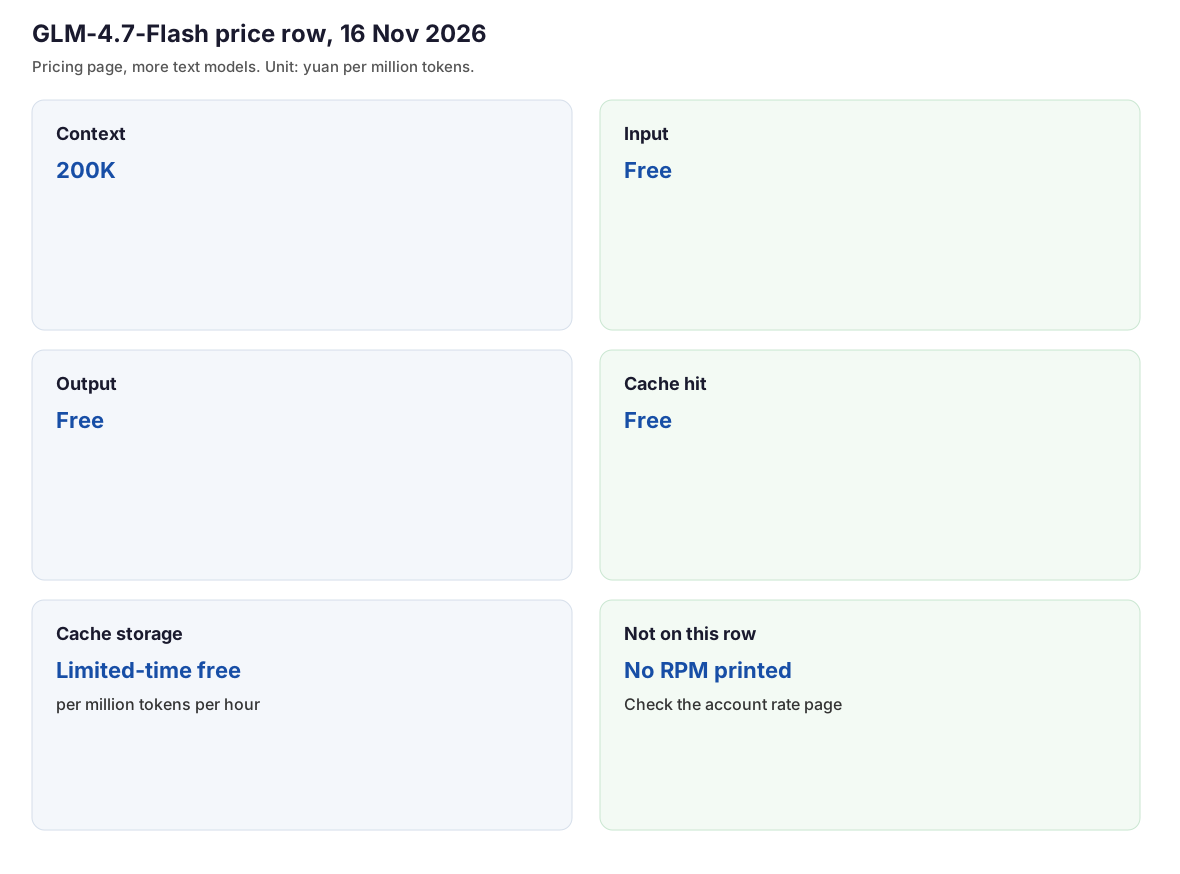
Under more text models, the pricing columns are context, input price, output price, cache storage, and cache hit. Input and output are priced in yuan per million tokens. Cache storage is yuan per million tokens per hour. The GLM-4.7-Flash row reads 200K, free, free, limited-time free, free. The last free cell is the cache hit. No requests-per-minute figure is printed on that row.
| Item | glm-4.7-flash, API id on the text card | GLM-4.6V-Flash, display name on the price page |
|---|---|---|
| Input price | Free | Free |
| Output price | Free | Free |
| Cache hit | Free | Free |
| Cache storage | Limited-time free | Limited-time free |
| Context cell | 200K | No number printed |
| API model string | glm-4.7-flash | Not printed on this row |
 🔍 View full resolution
The rate-limit page says concurrency caps differ by model and by account level. The numbers for a given account are on that account's rate-limits screen, not in the model card. Two failures share HTTP 429. Business code 1302 means the account reached its rate limit. Business code 1305 means this model is overloaded and the call should be retried later. Code 1211 means the model id does not exist. Codes 1210 and 1214 are parameter errors. Code 1113 means the account is past due, which is a billing failure sitting next to a row whose token cells say free.
The pricing FAQ says the billed amount follows the usage the API returns, the unit price in force for that call, and the account bill. When the page changes, the new price is the one then shown.
Pricing: docs.bigmodel.cn/cn/guide/start/pricing
Error codes: docs.bigmodel.cn/cn/faq/api-code
Account rates: bigmodel.cn/usercenter/proj-mgmt/rate-limits
Which call belongs on this id
Choose GLM-4.7-Flash if the payload is text, a Chinese console is acceptable, and the price cells say free for input and output. Use model id glm-4.7-flash, a standard model-API key, and sequential calls until the rate-limits screen shows the concurrency cap.
Choose the vision row if the input is an image. The display name is GLM-4.6V-Flash. Input, output, and cache hits on that row also say free. Read that model's own card for the API id. This price row does not print it. The text card header lists text only. A bad parameter comes back as 1210 or 1214. Code 1302 is the account rate limit.
Choose Groq's free-plan tab if the next job fans out in parallel and a missing concurrency number would stall it. That tab prints requests per minute. Copy the figure from the tab that day. This piece does not repeat it. Read the BigModel rate screen before switching. Back off longer on 1305 (the model is busy). Queue on 1302 (the account cap).