What the free tab prints
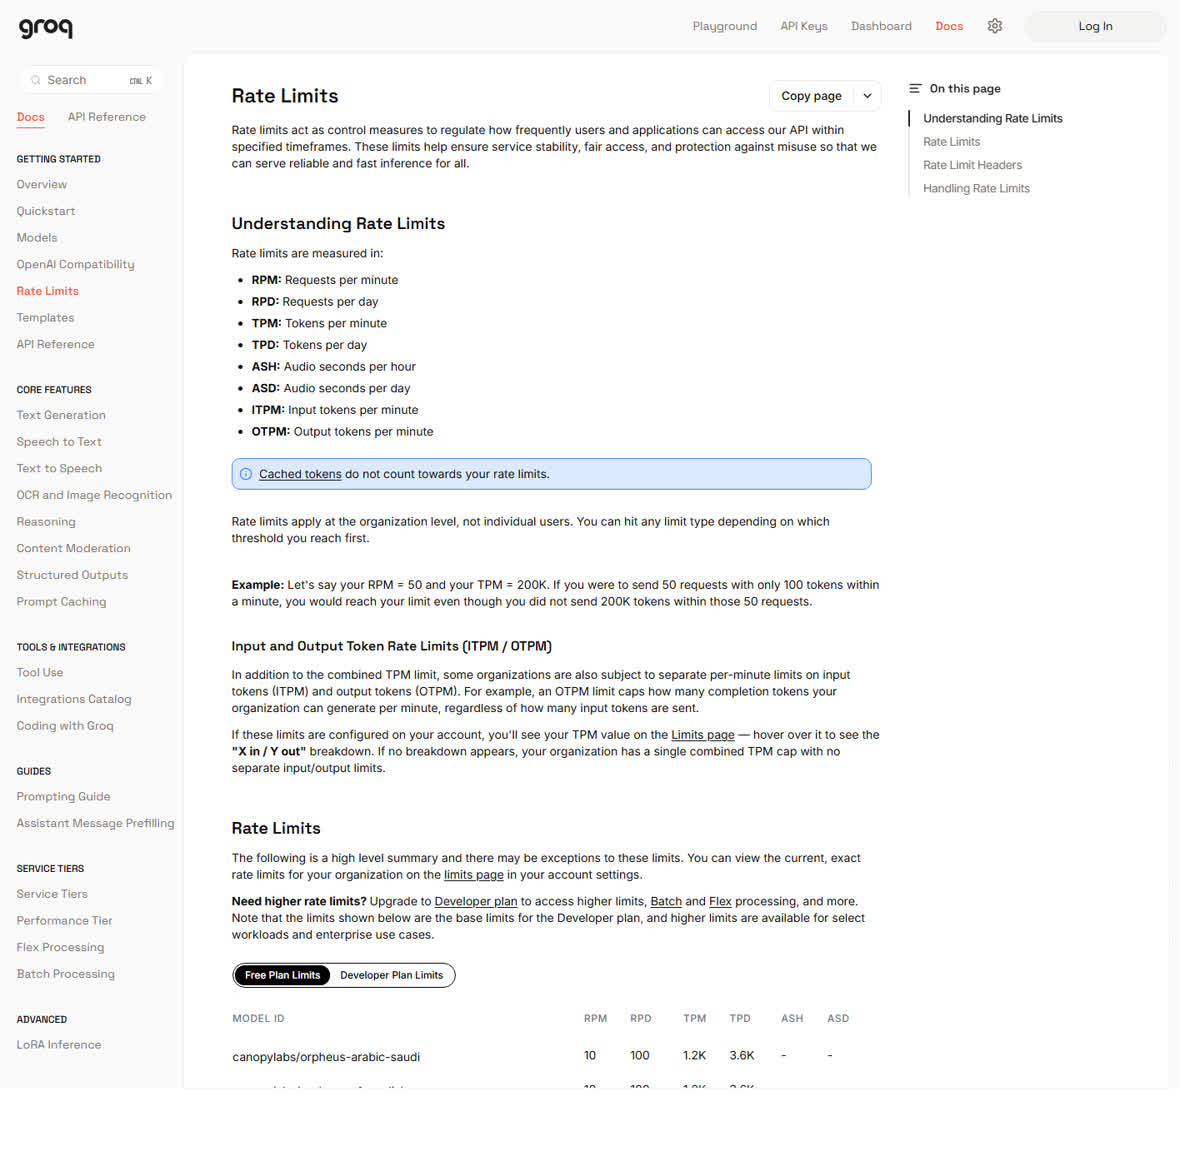
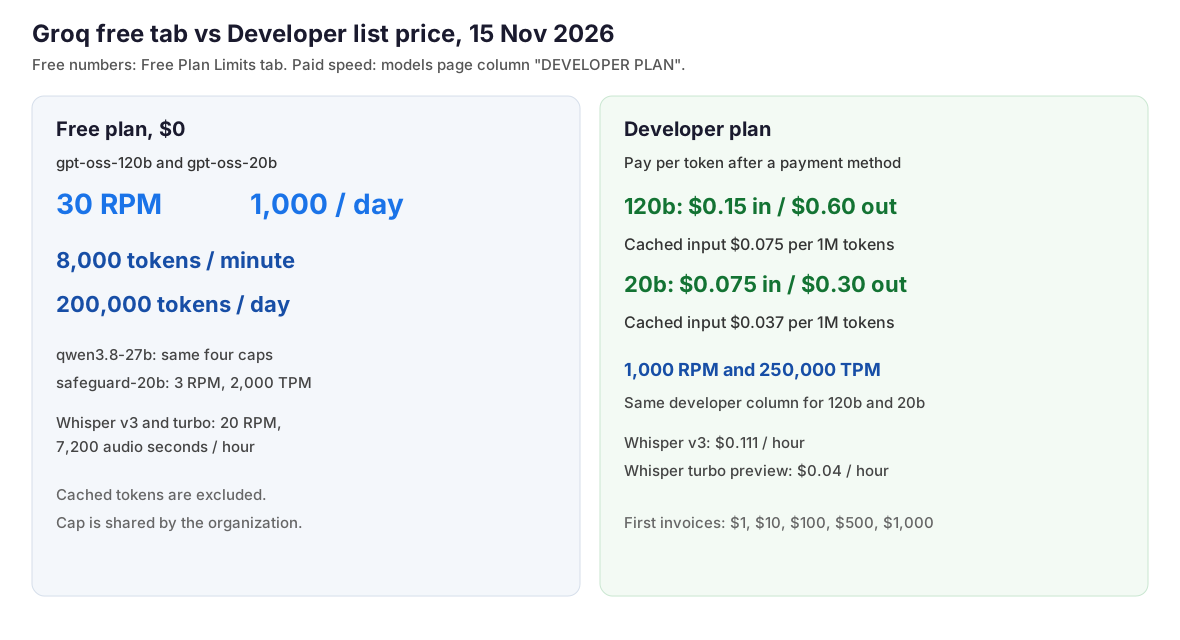
On 15 November 2026 the Groq rate-limits page opens with the Free Plan Limits tab selected. openai/gpt-oss-120b and openai/gpt-oss-20b share four caps: 30 requests per minute, 1,000 requests per day, 8,000 tokens per minute, and 200,000 tokens per day. qwen/qwen3.8-27b is on the same four numbers. openai/gpt-oss-safeguard-20b is tighter per minute: 3 RPM and 2,000 TPM, with the same 1,000 requests and 200,000 tokens per day. The cap belongs to the organization. Extra API keys do not add a second pool.
A sentence above the tabs says the table shows base limits for the Developer plan. That line fights the selected tab, and it fights the models catalog: the column headed RATE LIMITS (DEVELOPER PLAN) prints 1,000 RPM and 250,000 TPM for gpt-oss-120b. Read free caps from the selected tab. Read paid throughput from that column header. The page also says the table is a summary and the account Limits screen can differ.
 🔍 View full resolution
Cached tokens do not count toward the caps. The blue note sits above the table.
Signup: console.groq.com
Rate limits: console.groq.com/docs/rate-limits
Developer prices on the model page
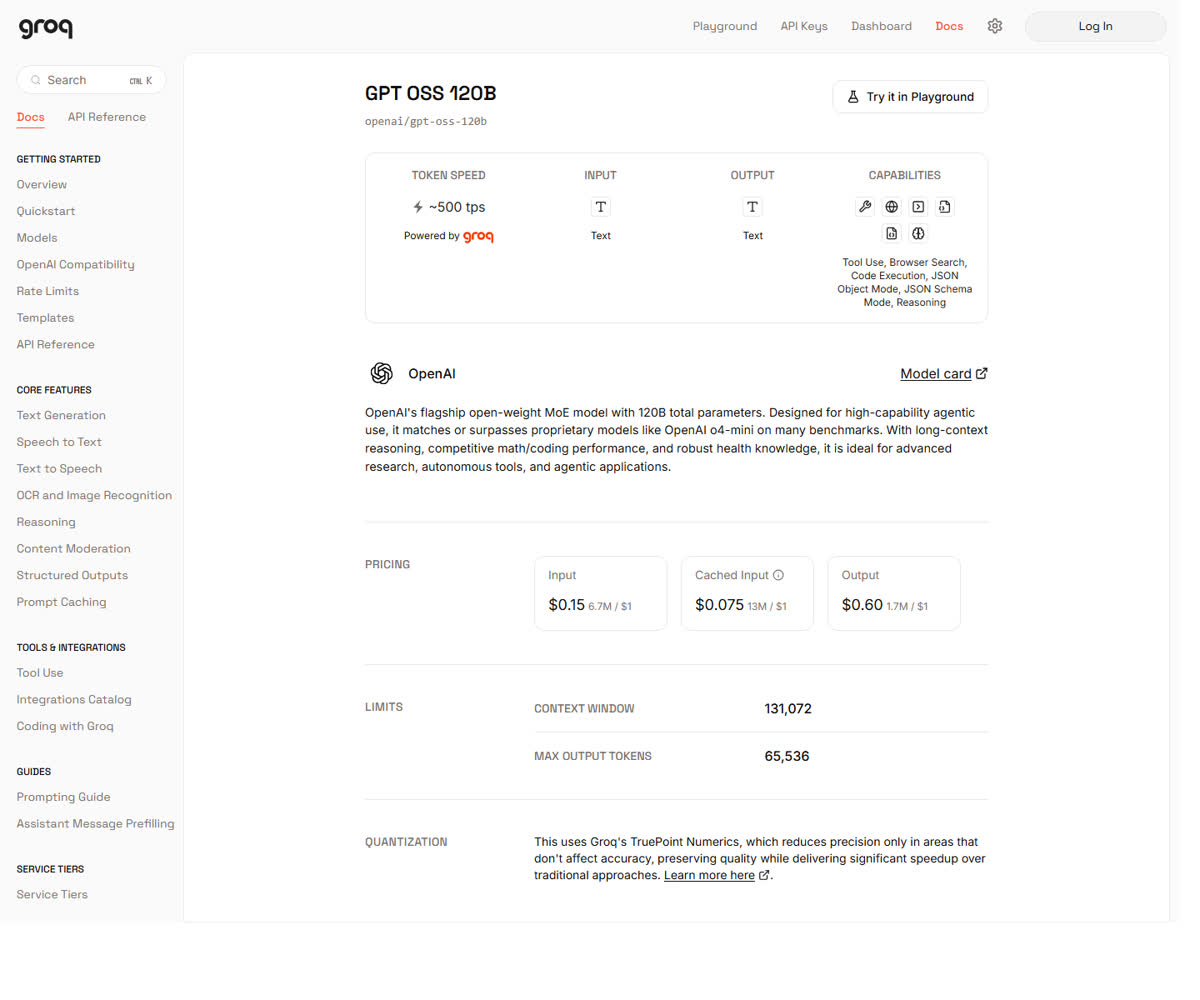
The gpt-oss-120b model page, same day, prints input $0.15 per million tokens, cached input $0.075, and output $0.60. Context window: 131,072 tokens. Max output: 65,536. The page labels speed at about 500 tokens per second. That label is Groq's, not an independent timing. gpt-oss-20b is listed at $0.075 input, $0.037 cached input, and $0.30 output, with a speed label of about 1,000 tokens per second. Its developer column matches 120b: 1,000 RPM and 250,000 TPM.
 🔍 View full resolution
The same page describes the layout: 120 billion parameters total, 5.1 billion active per forward pass, 128 experts, top-4 routing. That is a spec sheet, not a quality ranking.
 🔍 View full resolution
| Model | Plan | Price | Published cap |
|---|---|---|---|
| gpt-oss-120b | Free | $0 | 30 RPM, 1,000/day, 8,000 TPM, 200,000 TPD |
| gpt-oss-120b | Developer | $0.15 in, $0.075 cached, $0.60 out | 1,000 RPM, 250,000 TPM |
| gpt-oss-20b | Free | $0 | Same four free caps as 120b |
| gpt-oss-20b | Developer | $0.075 in, $0.037 cached, $0.30 out | 1,000 RPM, 250,000 TPM |
| whisper-large-v3 | Free | $0 | 20 RPM, 7,200 audio seconds/hour, 28,800/day |
| whisper-large-v3 | Developer | $0.111 per hour | 300 RPM, 200,000 audio seconds/hour |
Prices are per million tokens unless the row says per hour. Whisper turbo is priced at $0.04 per hour on the developer catalog and sits in the preview section, which Groq says is for evaluation and can be removed on short notice.
120b model page: console.groq.com/docs/model/openai/gpt-oss-120b
20b model page: console.groq.com/docs/model/openai/gpt-oss-20b
Which cap fills first
Arithmetic from the published free caps, not a timed run: four requests of 2,000 tokens in the same minute use the whole 8,000 TPM allowance. A fifth request in that minute is over the token cap while 26 of the 30 RPM slots are still open. Across a full day, 1,000 requests and 200,000 tokens average 200 tokens per request if both ceilings are used up together. A long system prompt spends the day cap before the request cap.
Whisper on the free tab, both v3 and turbo: 20 RPM, 2,000 requests per day, 7,200 audio seconds per hour, 28,800 audio seconds per day. Developer prices on the models catalog: whisper-large-v3 at $0.111 per hour (300 RPM, 200,000 audio seconds per hour) and the turbo preview at $0.04 per hour (400 RPM, 400,000 audio seconds per hour).
Moving to Developer requires a payment method: card, US bank account, or SEPA debit. The billing FAQ says the upgrade itself is not an immediate charge. For standard accounts, invoices then fire at cumulative usage of $1, $10, $100, $500, and $1,000, or at month end. After lifetime usage passes $1,000, standard accounts are billed monthly only. India accounts do not use the $500 and $1,000 tiers. An India billing address uses $1, $10, and then every additional $100.
Billing FAQ: console.groq.com/docs/billing-faqs
Which plan to use
Stay on Free if: 200,000 tokens a day and 8,000 tokens a minute cover the job, and a 429 is an acceptable stop. gpt-oss-20b and gpt-oss-120b share that free ceiling. The smaller model does not add free tokens.
Move to Developer if: the job needs the 1,000 RPM and 250,000 TPM column, or paying $0.15 / $0.60 per million tokens on gpt-oss-120b is cheaper than stopping at 200,000 tokens. The first invoice is month-end or the $1 usage mark, whichever comes first. Set a spend limit on the Developer plan. The FAQ lists spend limits as a Developer feature.
Use gpt-oss-20b when the bill is the constraint. One million input tokens plus one million output tokens cost $0.375 on 20b ($0.075 + $0.30) and $0.75 on 120b ($0.15 + $0.60).
Leave Whisper turbo out of a long-term budget. The models page files it under preview.