Copy an id that is still on the list
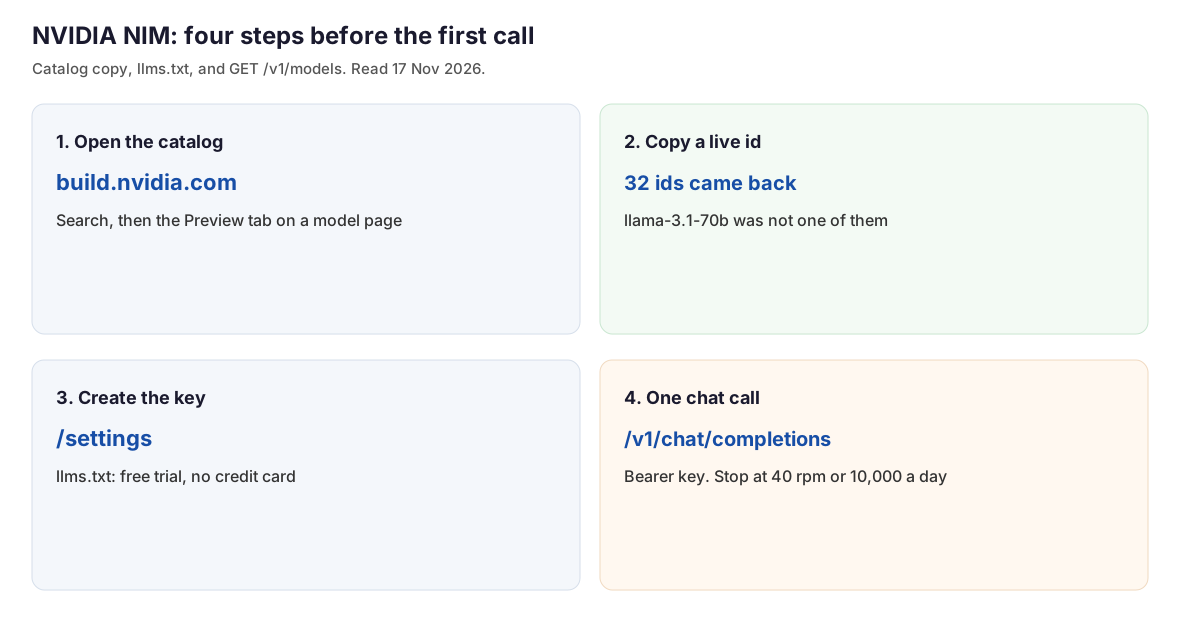
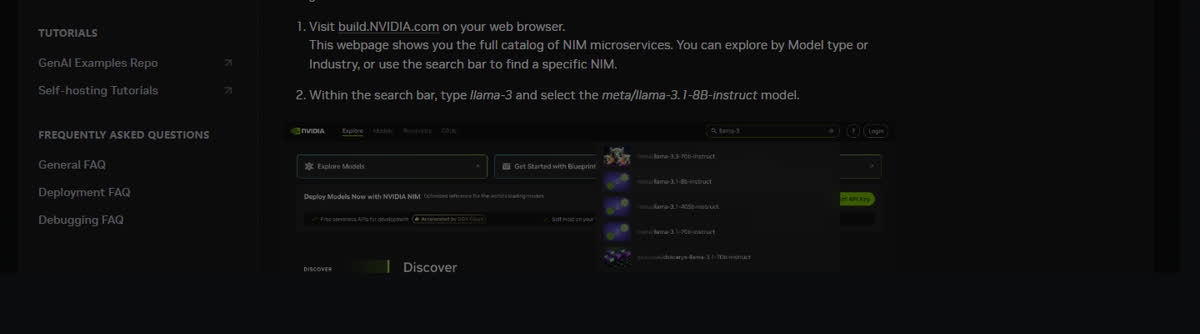
On 17 November 2026, GET https://integrate.api.nvidia.com/v1/models returned HTTP 200 and 32 model ids. No API key was sent with that request. The same day, build.nvidia.com/llms.txt told callers to use nvidia/llama-3.1-70b-instruct. That id was not in the 32. The quickstart at the docs site still says to search for llama-3 and open meta/llama-3.1-8B-instruct. The page says it was updated 3 months ago. That id was not in the 32 either.
Ids that were on the list and read as chat models include google/gemma-4-31b-it, openai/gpt-oss-20b, nvidia/nemotron-3.5-lightning-30b-a3b, and z-ai/glm-5.3-flash. The same list also holds embed and detector ids, including nvidia/embed-qa-4 and nvidia/ai-synthetic-video-detector. A chat call needs a chat id. Copy the id from the model page you opened, then check it against /v1/models before it goes into code.
 🔍 View full resolution
 🔍 View full resolution
Catalog: build.nvidia.com/search
Model list: integrate.api.nvidia.com/v1/models
Quickstart: docs.api.nvidia.com/nim/docs/api-quickstart
The key, then one chat completion
llms.txt says every model offers a free trial tier and that no credit card is required. The key is created at https://build.nvidia.com/settings. The base URL is https://integrate.api.nvidia.com/v1. The header is Authorization: Bearer plus the key. Chat calls go to /v1/chat/completions, which the file says is the OpenAI chat-completions shape.
The quickstart click path is still usable, and its sample model is not. Open build.nvidia.com, search, and use the Preview tab to send one line in the browser. On the model page, Get API Key asks for an email and joins the Developer Program. The copied Python still contains the placeholder API_KEY_REQUIRED_IF_EXECUTING_OUTSIDE_NGC. Replace that placeholder, and also replace the model id. A completion was not sent for this page. The check stopped at the model list, llms.txt, and the quickstart.
A first body that matches the file, with an id that was on the 17 Nov list: model set to google/gemma-4-31b-it, and messages with one user line. When that id leaves the list, swap it. Do not fall back to the llama id in llms.txt.
Get a key: build.nvidia.com/settings
Try it: build.nvidia.com/search
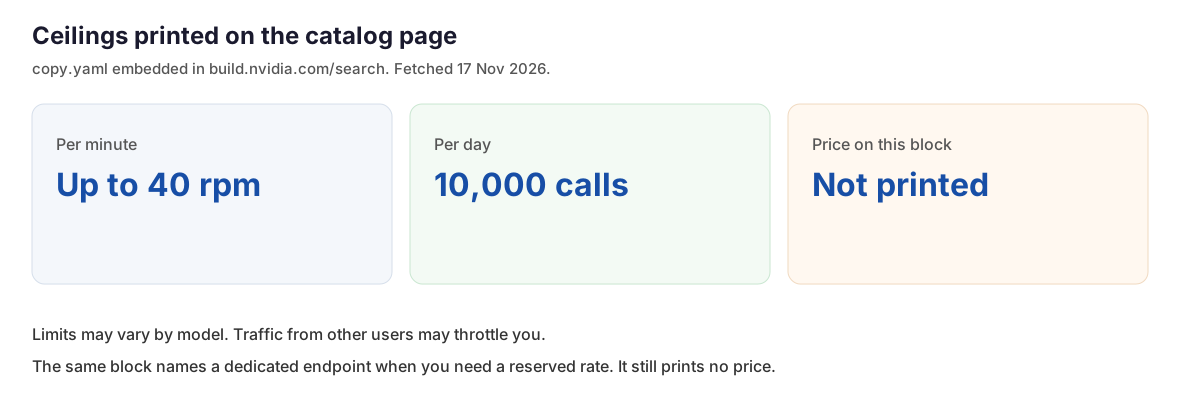
40 a minute, 10,000 a day, no price on the block
The catalog page embeds a copy block. Fetched 17 November 2026, requestsPerMinute is the string "Up to 40 rpm" and requestsPerDay is "10,000 requests per day". The detail line says these are the maximum requests accepted in a timeframe, that limits may vary by model, and that traffic from other users may cause throttling. For a reserved rate, the same block points at a dedicated endpoint. It does not print a dollar or yuan price for that endpoint.
 🔍 View full resolution
| Source | What it prints | What to do with it |
|---|---|---|
| Catalog copy.yaml | Up to 40 rpm. 10,000 requests a day. May vary by model. | Stop when either ceiling hits. Fetched 17 Nov 2026. |
| llms.txt | Free trial, no credit card. Sample id nvidia/llama-3.1-70b-instruct. | Keep the trial line. Drop the sample id. It was not in the 32. |
| Quickstart | Click path, plus meta/llama-3.1-8B-instruct. Updated 3 months ago. | Keep the clicks. Drop the sample id. It was not in the 32. |
| GET /v1/models | 32 ids, HTTP 200, no key on the request. | Paste an id from this list. Example: google/gemma-4-31b-it. |
Dedicated endpoint note: docs.api.nvidia.com/nim/reference/models-1
Which door to open
Choose the model page if the first sentence should happen in the browser. Preview sends it. Get API Key sits on the same page. The email step joins the Developer Program.
Try it: build.nvidia.com/search
Choose google/gemma-4-31b-it if the code needs one chat id that was on the list on 17 Nov 2026. Recheck /v1/models the day you send it. Embed ids on that list are the wrong shape for this call.
Model list: integrate.api.nvidia.com/v1/models
Choose a dedicated endpoint if 40 requests a minute or 10,000 a day already stopped the job. The catalog block names that exit and prints no price. Read the deploy page before you assume a bill.
Docs: docs.api.nvidia.com/nim/reference/models-1
Stay on the quickstart if you only need the click order. Ignore the llama-3.1-8B id in step 2.
Quickstart: docs.api.nvidia.com/nim/docs/api-quickstart
Get a key: build.nvidia.com/settings