Three pages, one sentence, no stopwatch
On 17 Nov 2026 the comparison was the Ollama quickstart against two Groq pages: rate limits and supported models. Nobody timed a token. The question is where the first copy of a short prompt should go, and which model id each page will actually accept.
Ollama's local tab names gemma4:e2b. Groq's quickstart sample still passes llama-3.3-70b-versatile. The free-plan table and the models page both point at a different id from that sample, and the steps below follow the table.
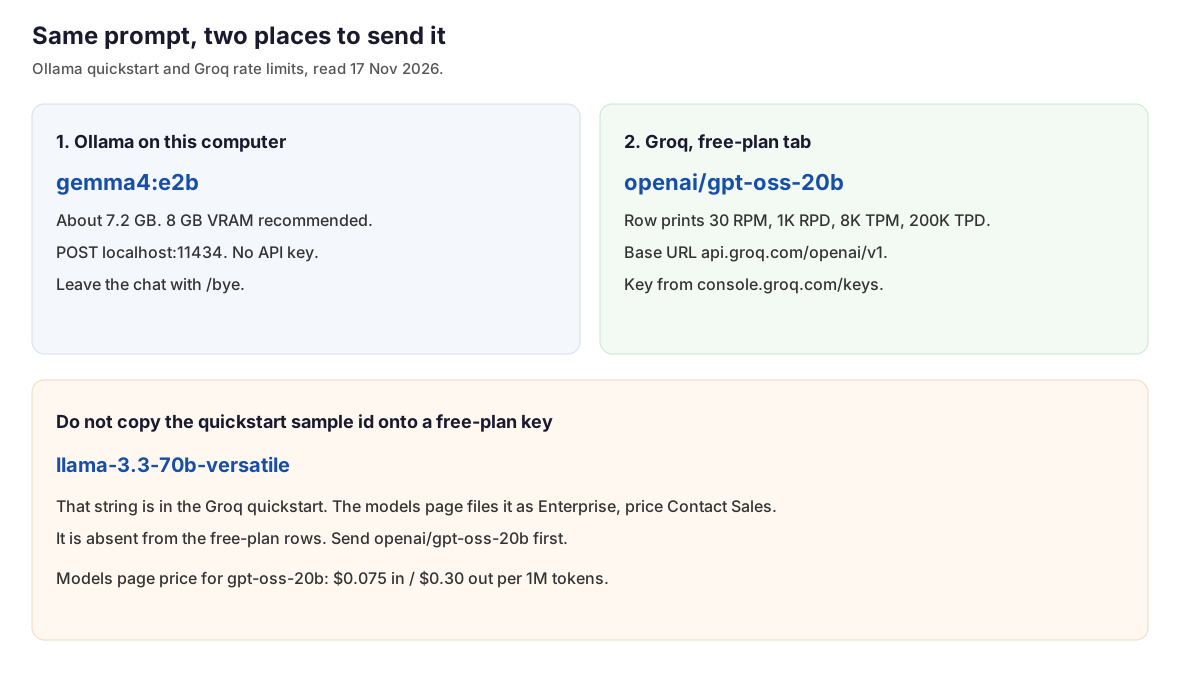
Install Ollama and call gemma4:e2b
The quickstart local tab says to download Ollama, then run ollama pull gemma4:e2b. The download is about 7.2 GB. The same note recommends 8 GB of VRAM, or unified memory on a Mac. A larger context window needs more memory. With less VRAM, Ollama can use system RAM and responses may be slower. On Linux, start the server with ollama serve if it is not already running.
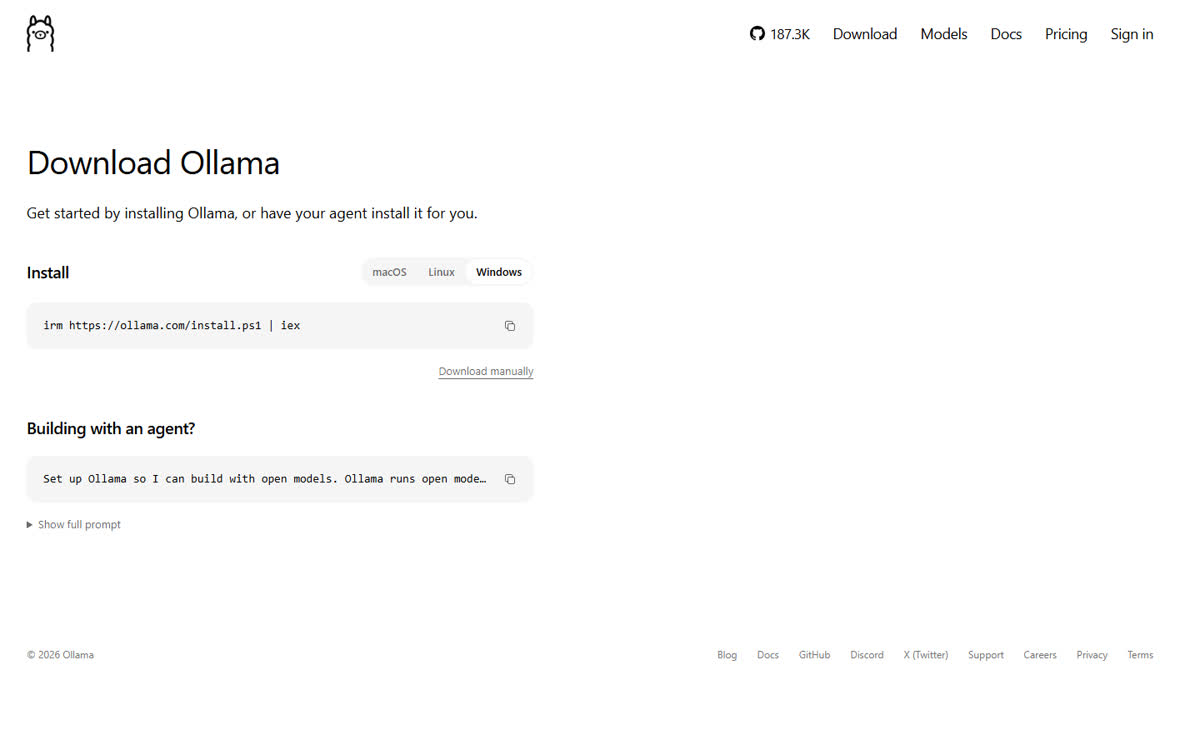
The download page shows macOS, Linux, and Windows. The Windows tab prints irm https://ollama.com/install.ps1 | iex. The page markup also includes curl -fsSL https://ollama.com/install.sh | sh.
Try it: ollama.com/download
After the pull, ollama run gemma4:e2b opens a chat on that computer. Type /bye to leave. A program can skip the chat and POST to http://localhost:11434/v1/chat/completions with "model": "gemma4:e2b" and no Authorization header. The answer is in choices[0].message.content. The same host also accepts http://localhost:11434/api/chat.
The cloud tab on that quickstart is a different product: it calls https://ollama.com/v1/chat/completions with an OLLAMA_API_KEY and the sample model gemma4:31b. Stay on the local tab if the point is to keep weights on the machine.
Create the Groq key, then change the sample id
Groq's quickstart starts with an API key. Put it in GROQ_API_KEY. The OpenAI compatibility page sets base_url to https://api.groq.com/openai/v1.
Sign-up: console.groq.com/keys
The Python sample on the quickstart sets model="llama-3.3-70b-versatile". On the models page that id sits on the Llama 3.3 70B Enterprise row, and both the price cell and the rate-limit cell say Contact Sales. The free-plan rows captured on 17 Nov 2026 do not list it. For the first call, replace the sample string with openai/gpt-oss-20b.
| Check | Ollama local, gemma4:e2b | Groq, openai/gpt-oss-20b |
|---|---|---|
| Where it runs | That computer, port 11434 | api.groq.com/openai/v1 |
| Key | None on the local tab | API key from console.groq.com/keys |
| Size or cap printed | About 7.2 GB download. 8 GB VRAM recommended | Free Plan Limits tab: 30 RPM, 1K RPD, 8K TPM, 200K TPD |
| Price on the vendor page | Local tab prints no per-request price | Models page: $0.075 input and $0.30 output per 1M tokens |
| Listed speed | Not listed on the quickstart | Models page lists 1000 tokens/sec for this id. This page did not time a run |
| Id to avoid copying blind | Cloud sample uses gemma4:31b and a key | Quickstart sample uses llama-3.3-70b-versatile |
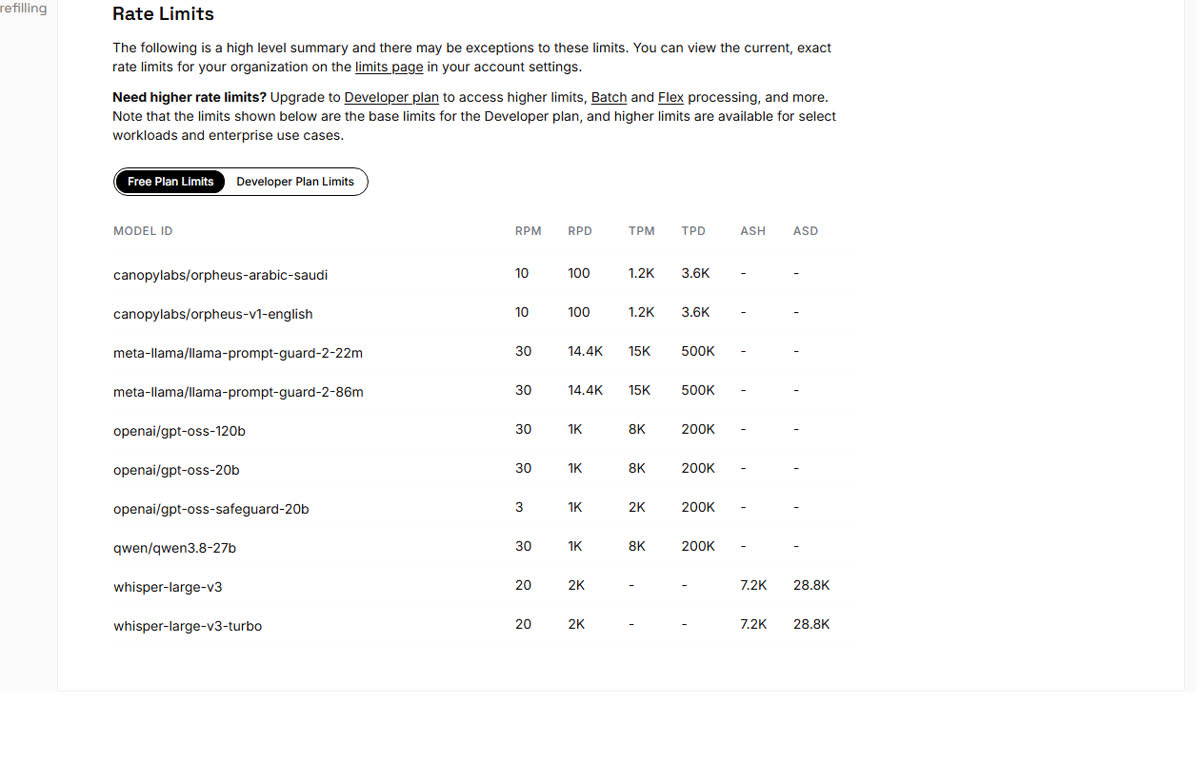
Read that screenshot with the sentence above the tabs. It says the limits shown below are the base limits for the Developer plan, while the selected tab is Free Plan Limits and the row is 30 RPM. The page also carries a Developer Plan Limits row for the same id: 1K RPM, 500K RPD, 250K TPM, and a dash for TPD. The models page's developer-plan column matches the 1K RPM and 250K TPM pair, next to the $0.075 / $0.30 price. Cached tokens do not count toward the cap. The cap is per organization, so a second key in the same org does not add a second allotment. A crossed cap returns HTTP 429. The account Limits page is what Groq calls the exact number for that org.
Which computer should hold the weights
Choose Ollama if: the prompt should stay on that machine, about 8 GB of VRAM or Mac unified memory is free, and 7.2 GB of disk is acceptable for gemma4:e2b. The first check is a reply from localhost:11434 with no key.
Choose Groq if: the weights should stay off the laptop, the model string is openai/gpt-oss-20b, and traffic stays inside the RPM on that organization's account Limits page. The Free Plan Limits tab prints 30 RPM, 1K RPD, 8K TPM, and 200K TPD for this id, and the sentence above the tabs calls those figures the Developer plan base. Send that id, not the quickstart sample.
Before a batch, open the Developer Plan Limits tab, the models-page price row, and the account Limits page. The two tabs do not print the same RPM. Before a client ships, open the quickstart, the rate-limits page, and the models page again. On 17 Nov 2026 the sample id and the free-plan rows already pointed at different models.